-
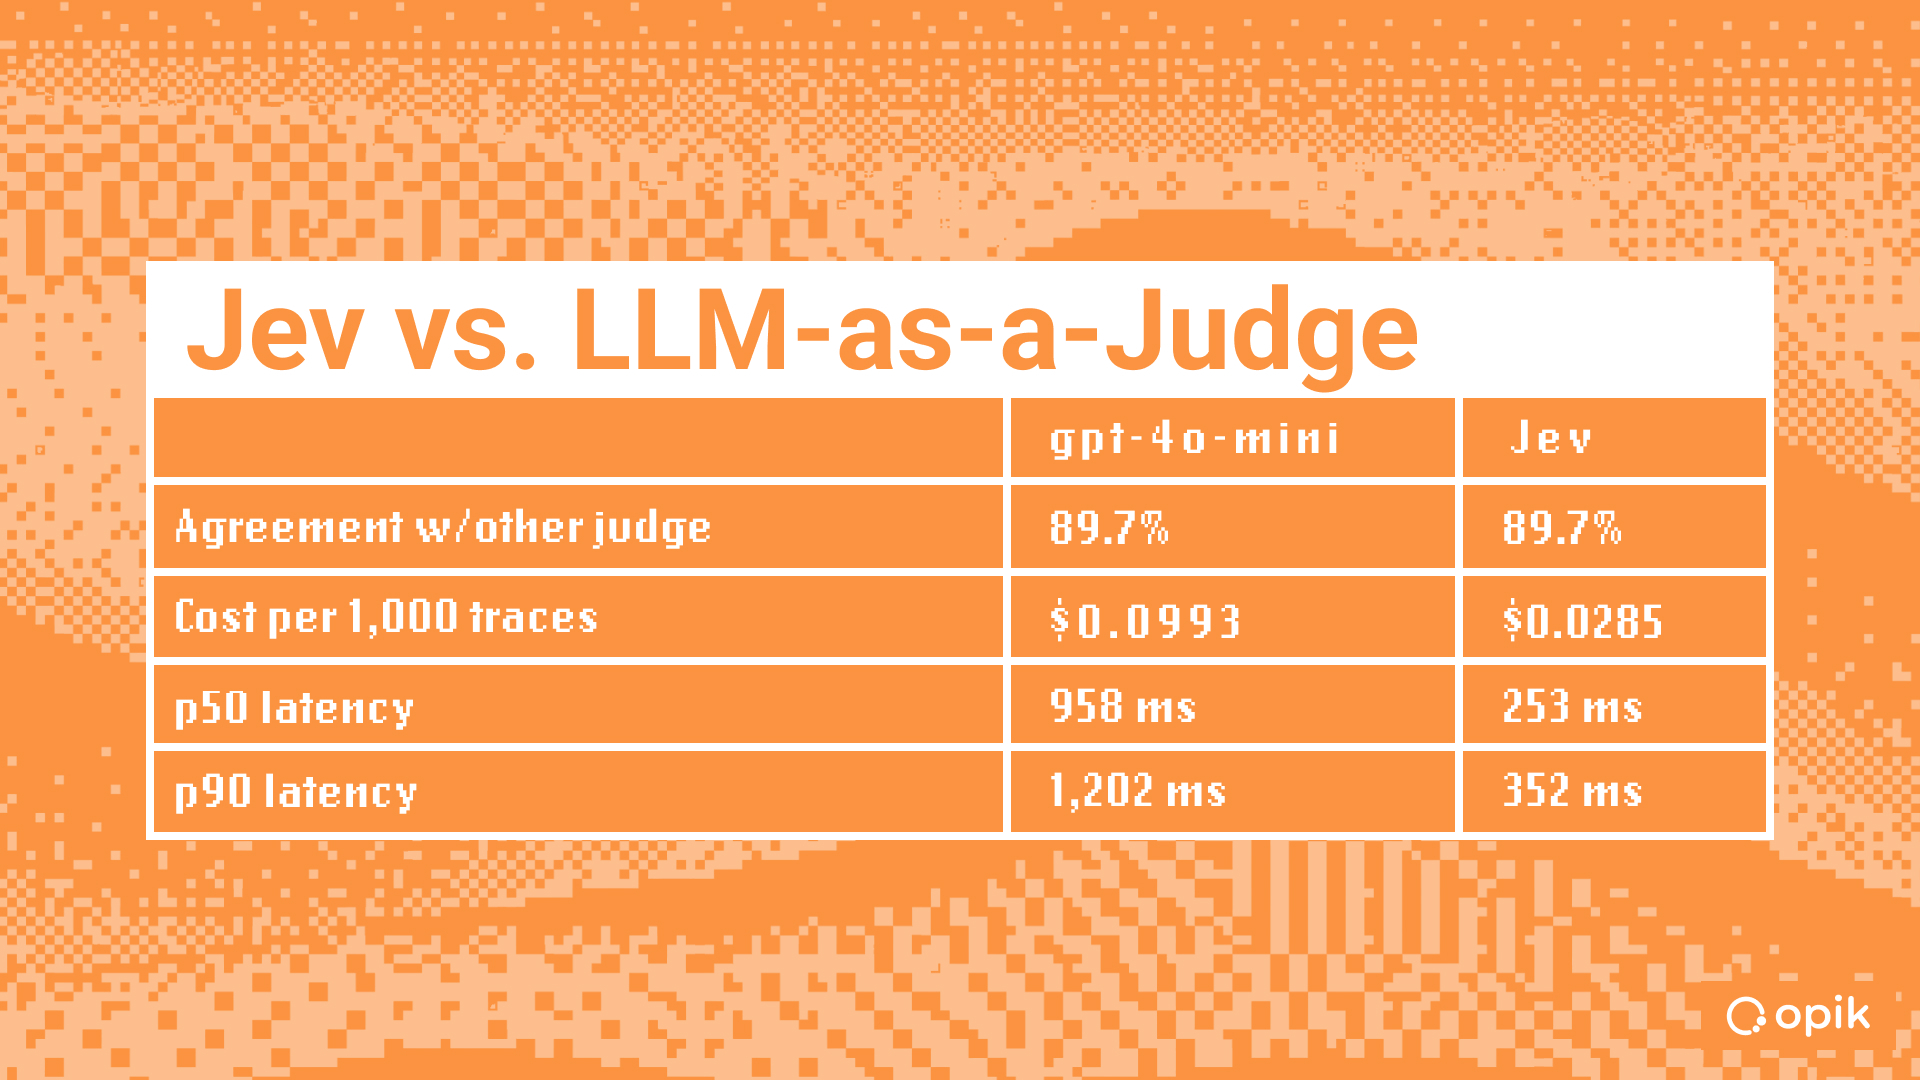
Jev vs. LLM-as-a-Judge for AI Evals
A model that answers yes/no questions instead of writing text came out 3.5× cheaper and 3.8× faster than our gpt-4o-mini…
-
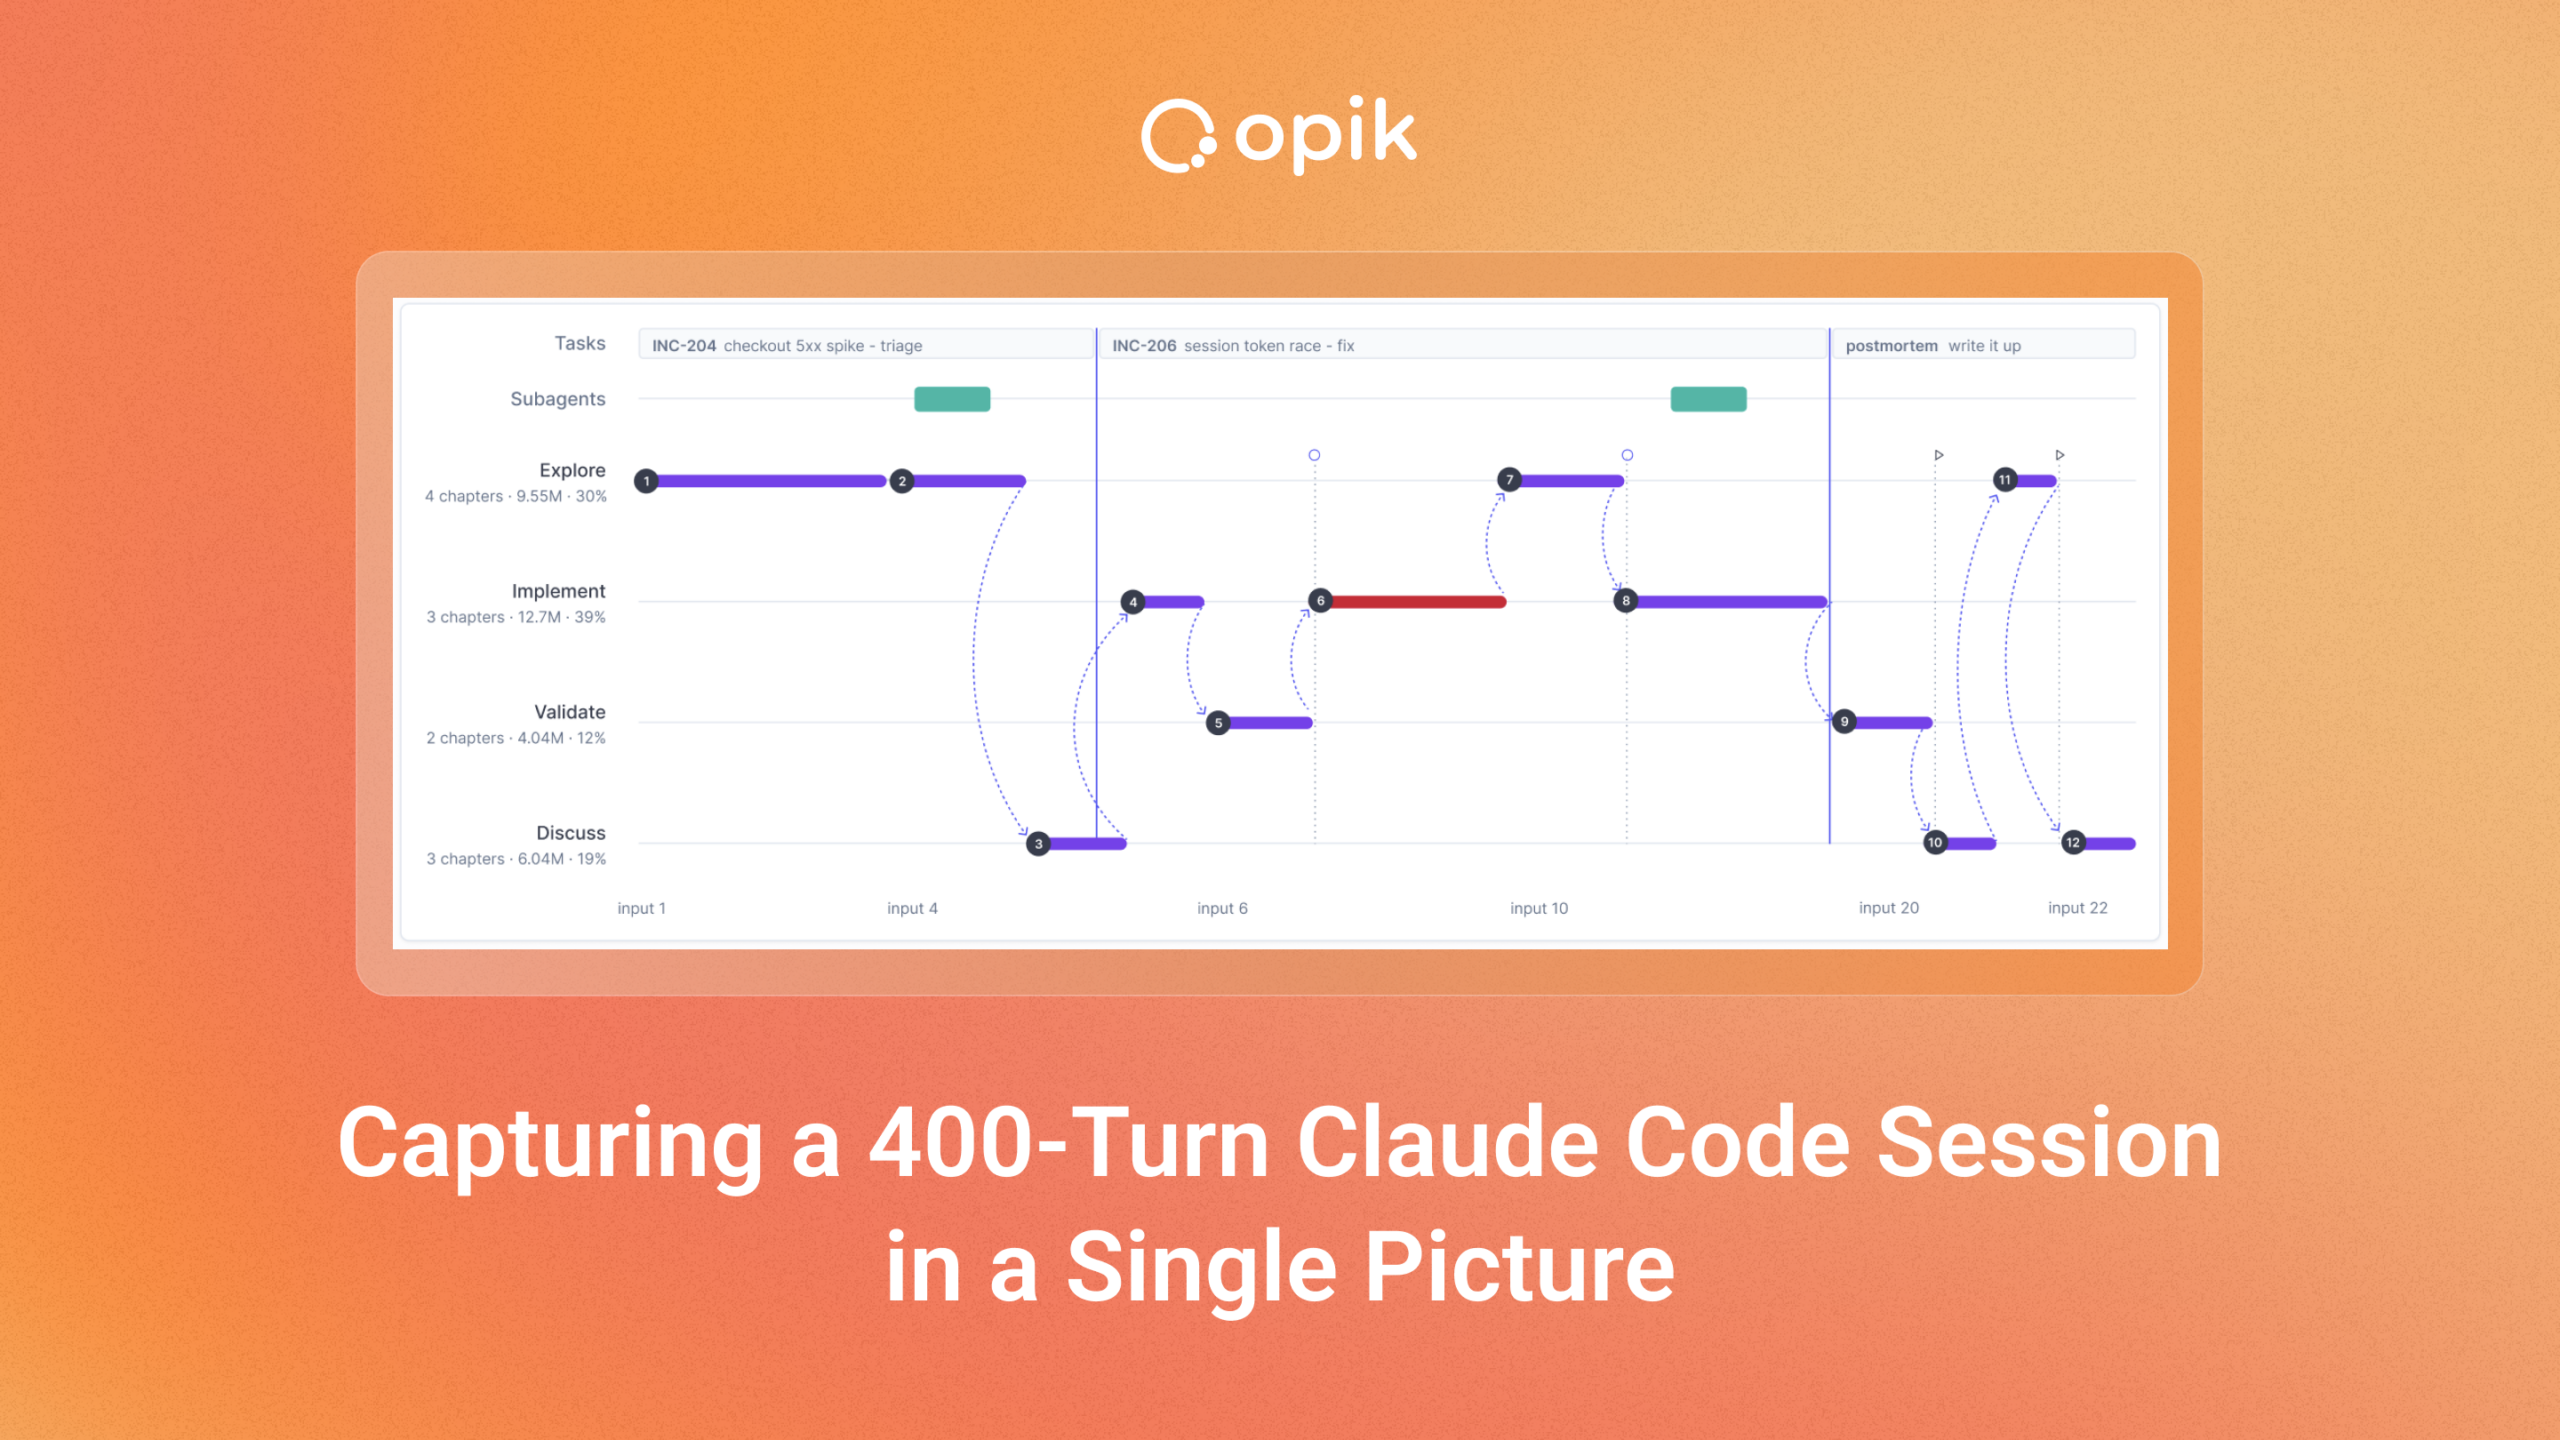
Capturing a 400-Turn Claude Code Session in a Single Image
We ran a small model over thousands of Claude Code session and discovered how people really use coding agents. Comet…
-
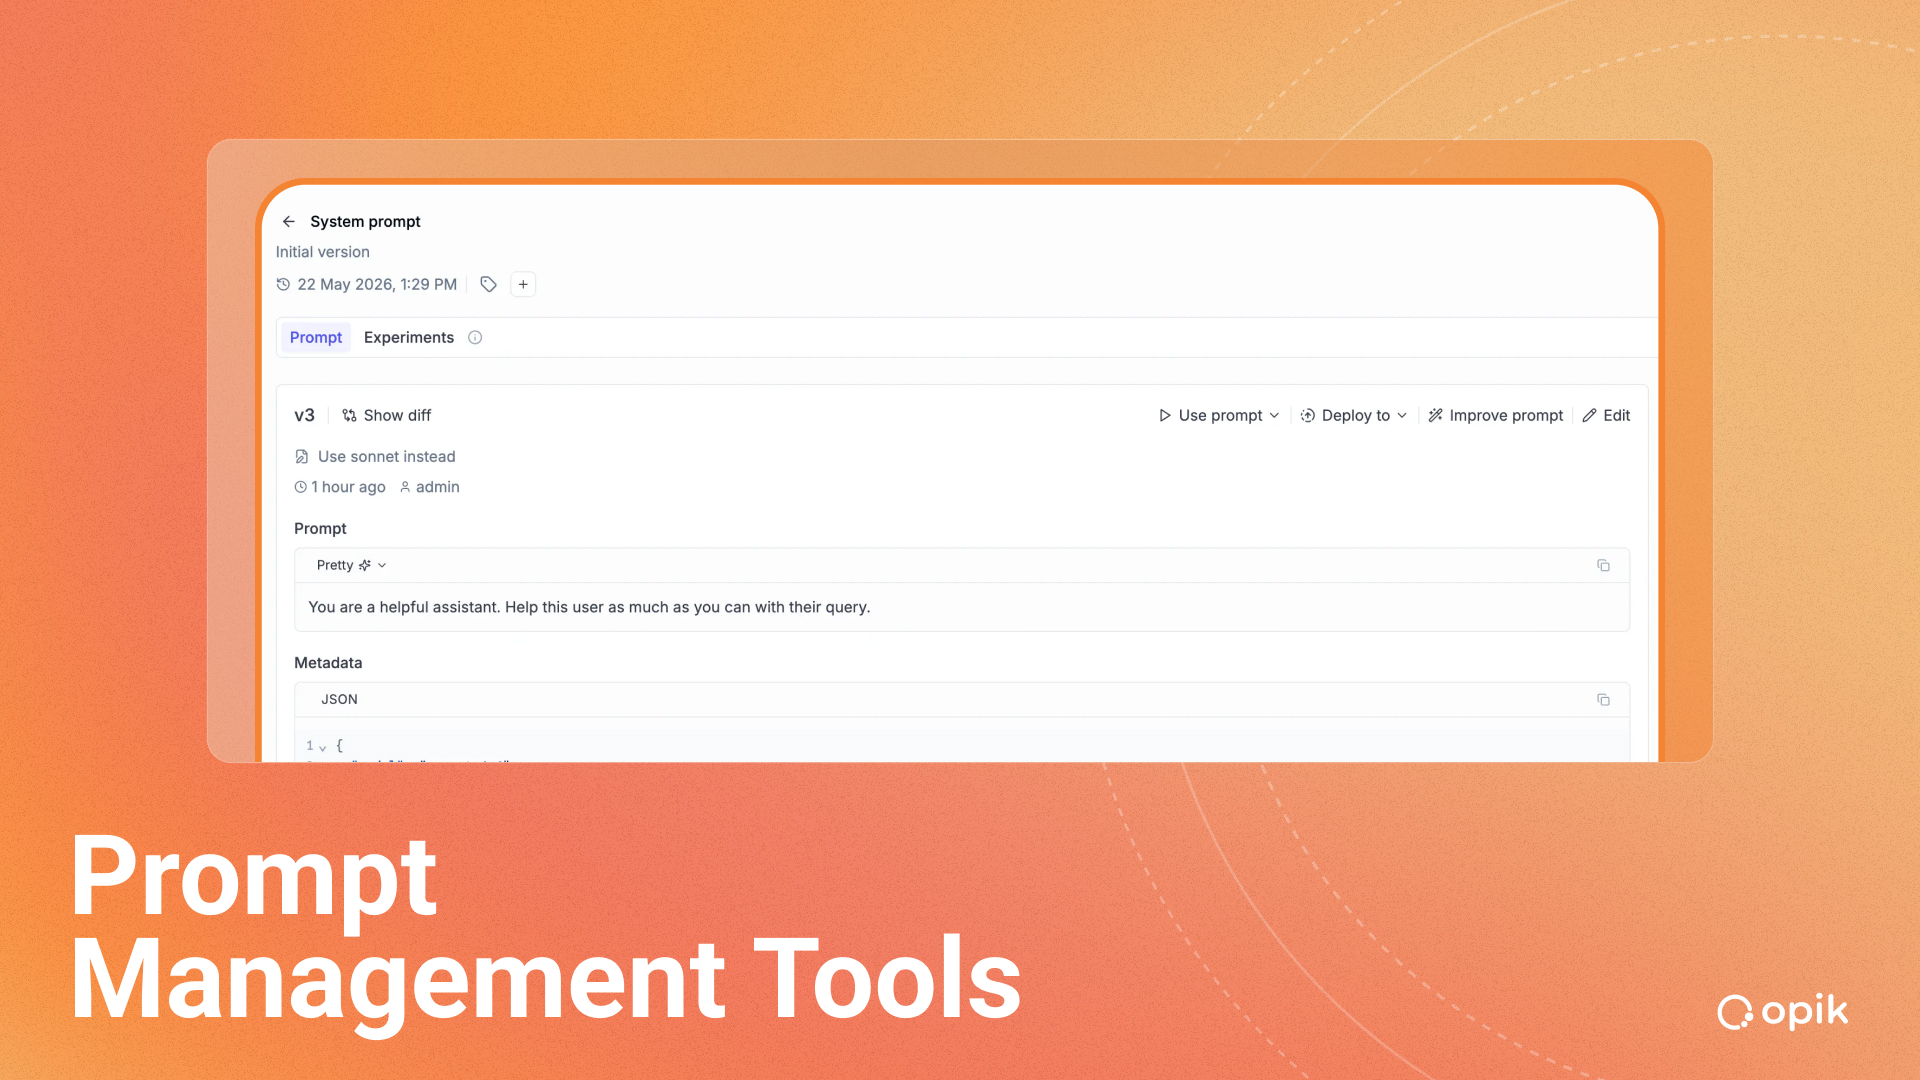
Prompt Management for AI Agents: The Best Tools Compared (2026)
Despite how often prompts change once an agent is live, most teams don’t have a real prompt management process. Somewhere…
-
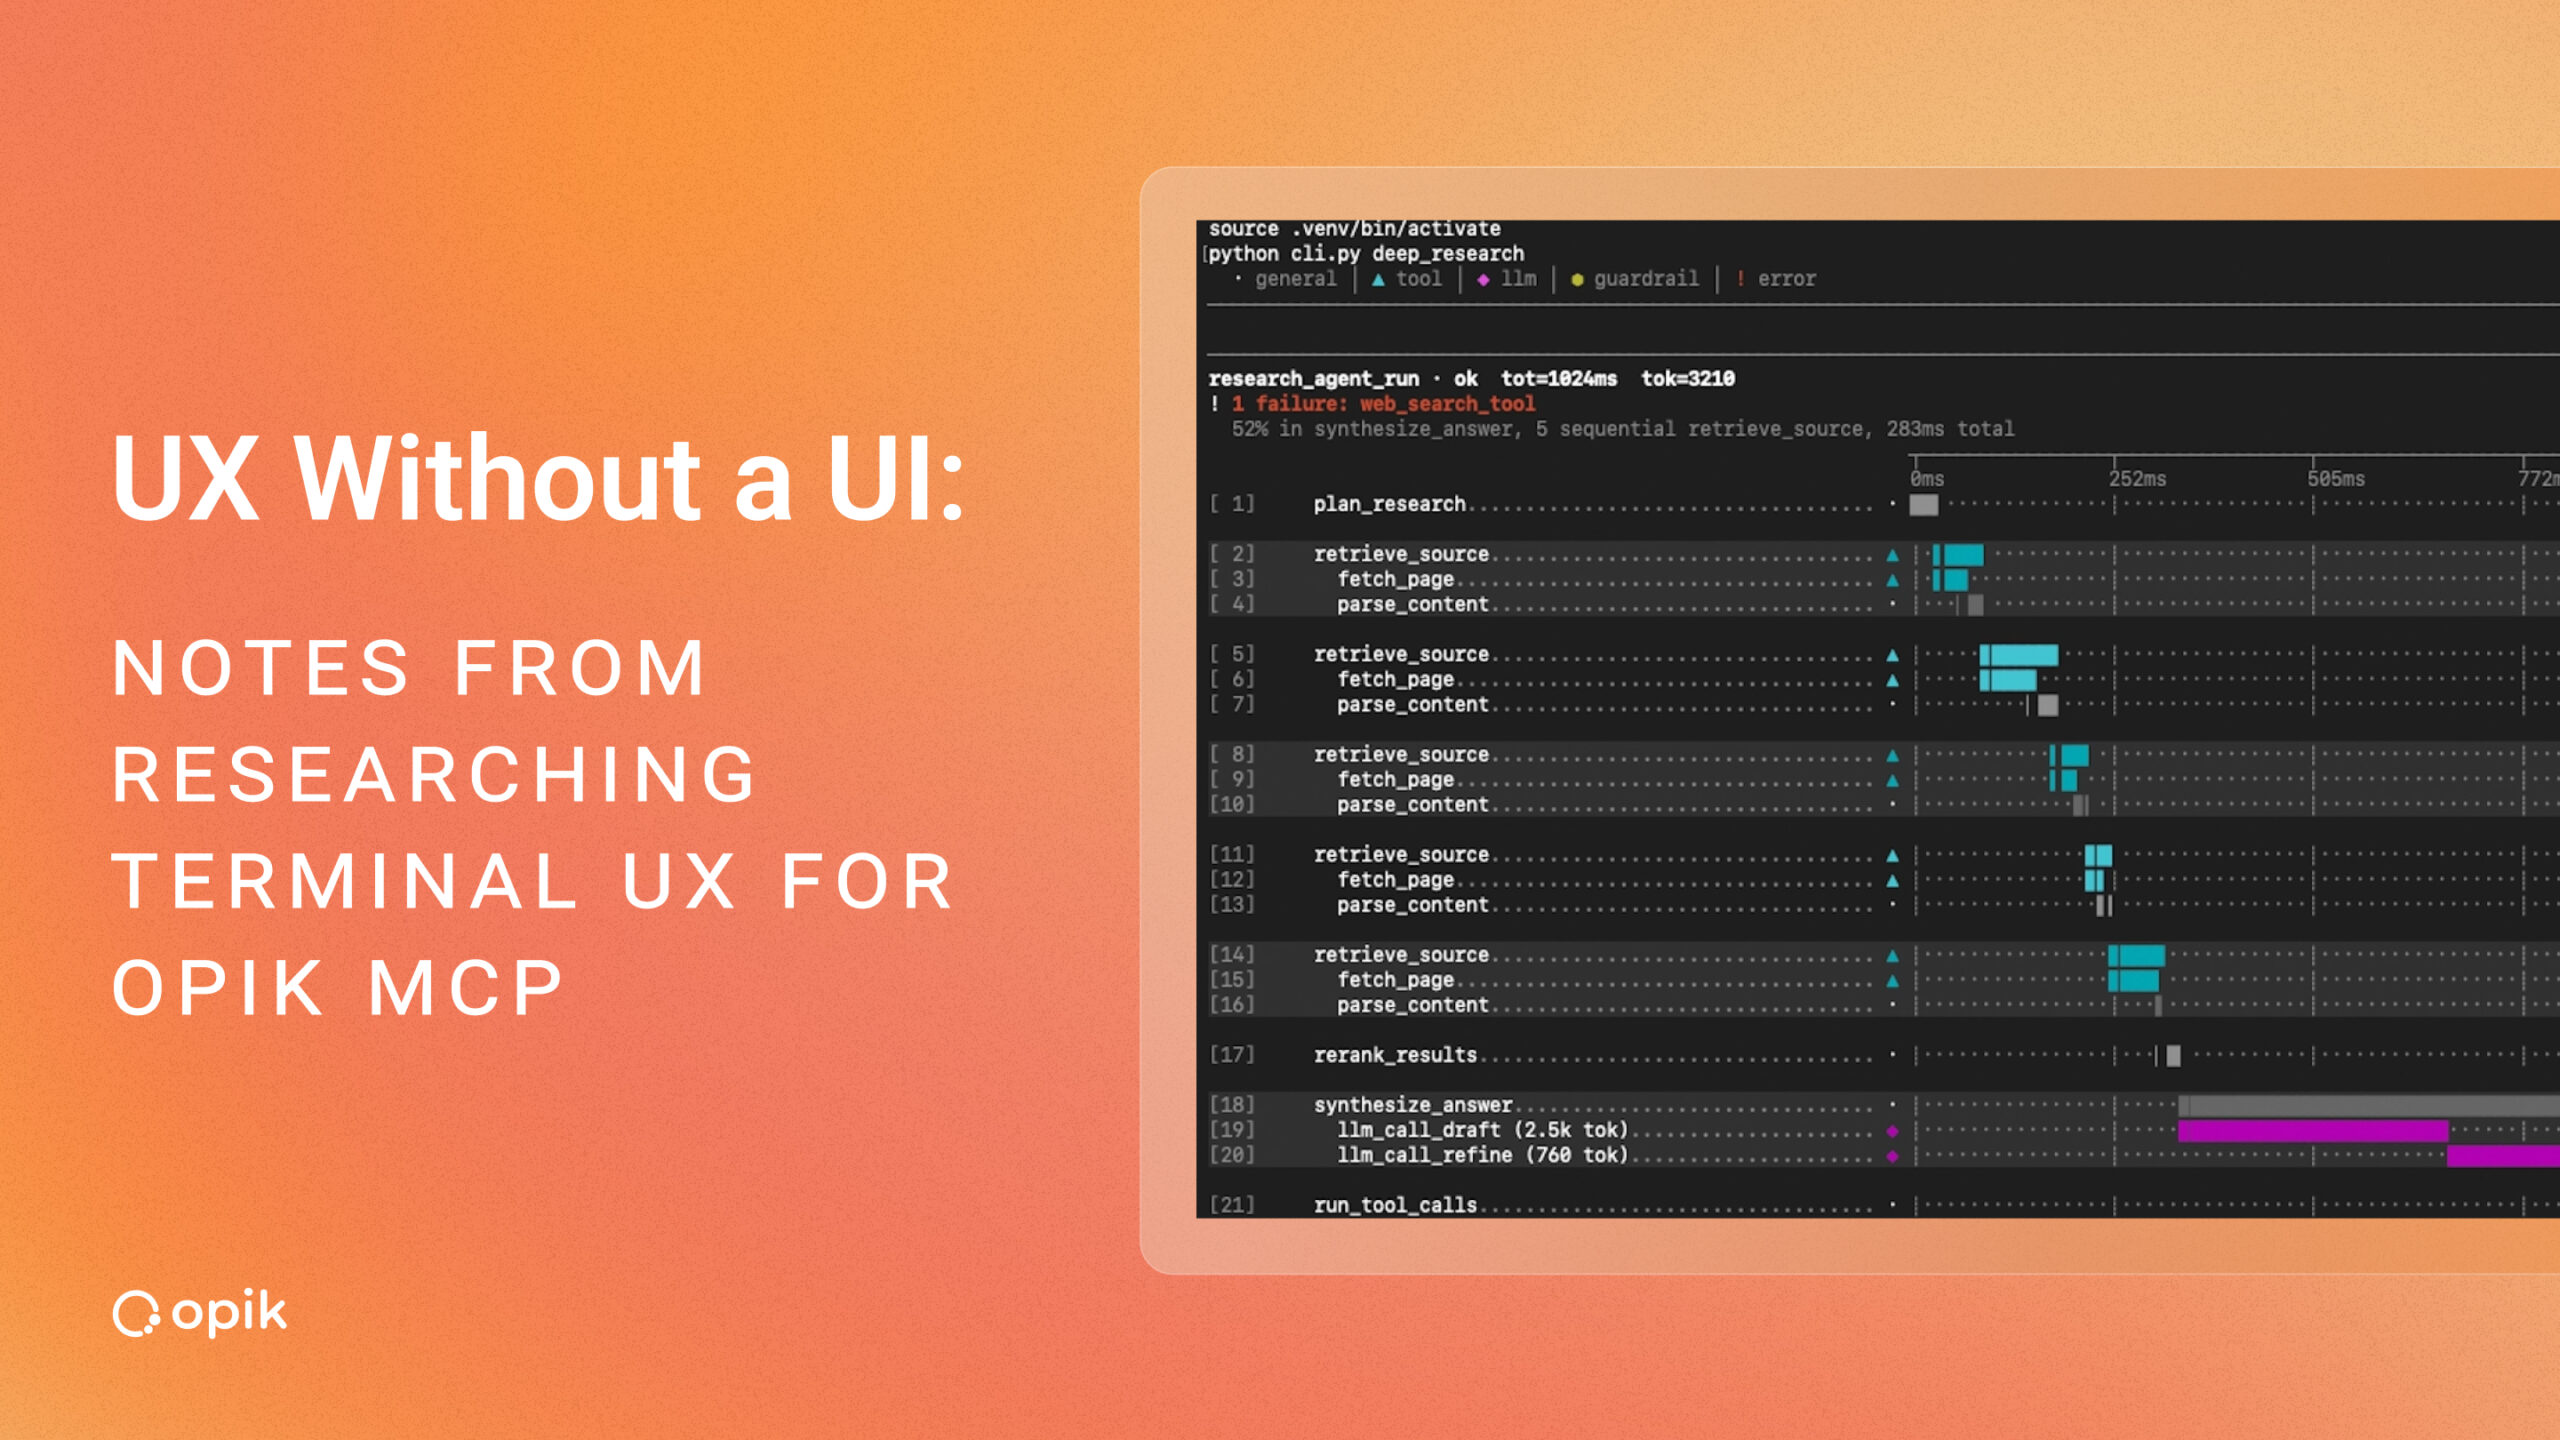
UX Without a UI: Notes from Researching Terminal UX for Opik MCP
The way developers interact with products is changing, and opening your app’s dashboard is no longer the obvious entry point.…
-
What is AI Observability? A Complete Guide to Debugging and Monitoring Modern AI Systems at Scale
Your new AI product is live. Infra dashboards are all green. Latency is low, error rates are flat, and CPU/GPU…
-
LLM Model Selection: How to Pick the Right Model for Every Agentic Task
Someone on your team defaulted to the latest and greatest model available, which is also the most expensive model. Maybe…
-
Best LLM Observability Tools of 2026: Top Platforms & Features
LLM applications are everywhere now, and they’re fundamentally different from traditional software. They’re non-deterministic. They hallucinate. They can fail in…
-
I Built a RAG Pipeline for F1 Team Radio, Then Made It Grade Itself
I wanted to see if I could build a RAG system that would output interesting and accurate F1 race weekend…
-
One Prompt, 24 Versions: How Digibee Builds Prompts with Opik to Power Their AI-Native Integration Platform
Digibee was founded 9 years ago to solve a key problem in enterprise tech stacks: tools didn’t integrate neatly with…
-
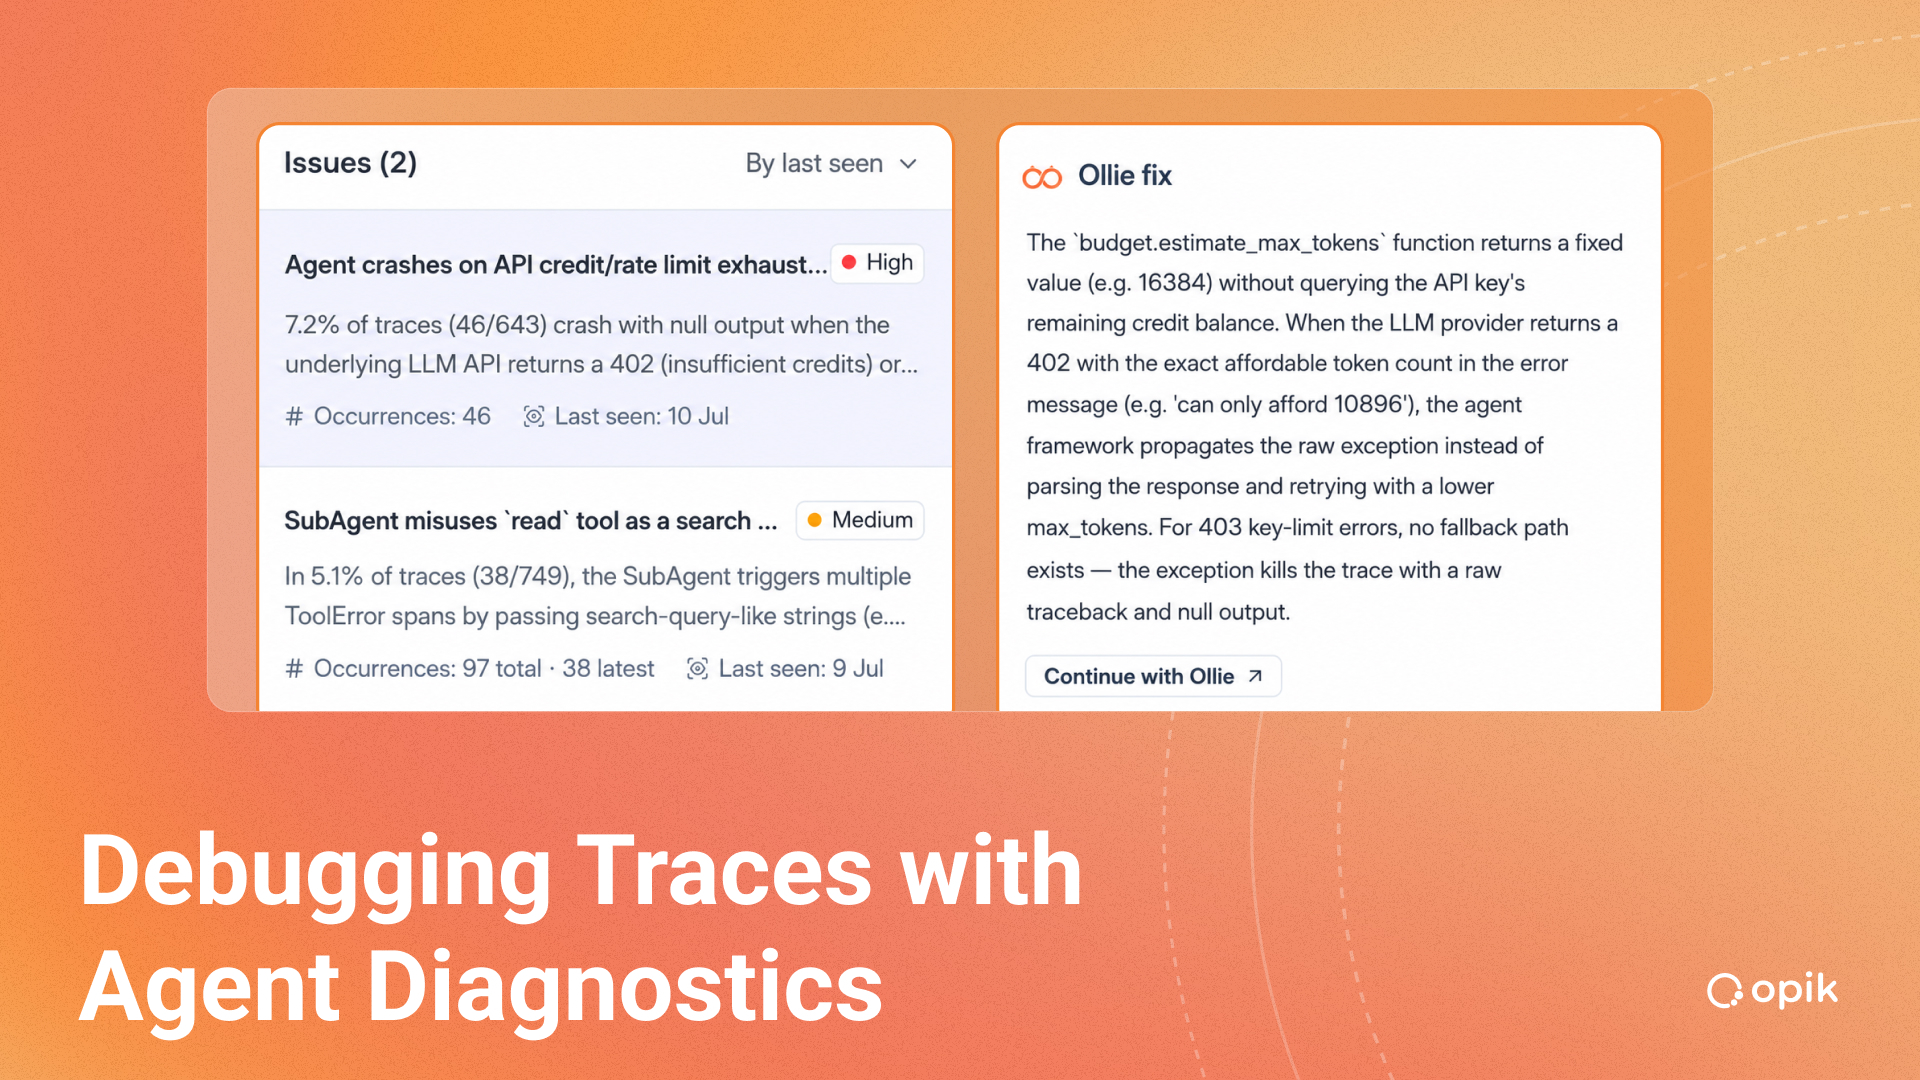
Beyond the Single Trace: How We Built Agent Diagnostics for Opik
If you run an AI agent in production, you already know the drill. Something goes wrong, a user complains, or…
Category: LLMOps

Get started today for free.
You don’t need a credit card to sign up, and your Comet account comes with a generous free tier you can actually use—for as long as you like.